
I learn a framework best when I make it solve a realistic problem. For Dapr, I did not want another hello-world service that stores one value in Redis. I wanted several services, asynchronous and synchronous communication, durable state, a long-running process, and one external secret.
That became a small case-management system. A case can arrive through a web interface, a REST endpoint, or a simulated mailbox. An OpenAI-backed agent triages it, and a workflow moves it through the rest of its lifecycle.
In this post, you will learn what Dapr contributed to that application and, equally important, where the abstraction stops. You will not find a detailed explanation of uv workspaces and local source references here. If those topics are new to you, my earlier posts Structuring Python projects with uv and Making larger Python projects work with uv, from source to Docker provide the background. Here, you can focus on Dapr and how the building blocks work together.
The mental model that made Dapr click for me#
Dapr is a runtime for distributed applications. Its APIs cover recurring integration concerns such as messaging, state, service invocation, bindings, secrets, and durable workflows.
The central idea is the sidecar. Each application process talks over HTTP or
gRPC to a nearby daprd process. The sidecar then talks to Redis, another Dapr
application, Kubernetes, or whichever component implements the requested
capability.
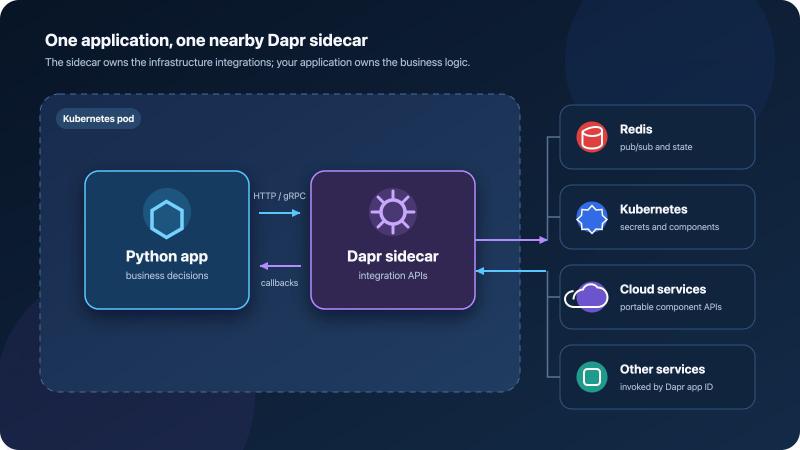
Your application talks to a nearby Dapr sidecar. The sidecar handles the integration with infrastructure and other Dapr applications.
Traffic flows in both directions:
- Your application calls Dapr to publish an event, store state, invoke another application, or retrieve a secret.
- Dapr calls your application to deliver a message or trigger an input binding.
On Kubernetes, annotations cause the Dapr injector to add the sidecar container
to each pod. During local development, dapr run -f starts the applications and
their sidecars together.
Component YAML connects a logical name such as casemgmt-pubsub to a concrete
implementation such as Redis Streams. That removes infrastructure clients from
your application code. It does not make every backend perfectly interchangeable:
component capabilities and operational behaviour still differ, so changing a
backend deserves testing.
The application I built#
The system has five Python services and Redis. All Python services come from one uv workspace and one container image, but each runs as a separate process and Dapr application.
Dapr does not require you to put multiple services in one image. I chose that
approach because these services belong to the same learning application, share
the ccm-common package, and are resolved by one lockfile. The image contains
all service entry points, while each Kubernetes Deployment selects one command,
such as ccm-frontend or ccm-case-service. For this project, that means you
build and distribute one version-aligned artifact instead of managing five
nearly identical images. The trade-off is tighter release coupling and a larger
artifact, so independently owned production services may be better served by
separate images.
| Service | Dapr app ID | Responsibility |
|---|---|---|
frontend | frontend | HTMX interface for creating and inspecting cases |
intake-api | intake-api | REST gateway that publishes intake events |
mail-ingestion | mail-ingestion | Turns mock email into intake events on a schedule |
case-service | case-service | Owns case state and runs the lifecycle workflow |
agent | agent | Uses OpenAI to classify and route a case |
redis | none | Backs pub/sub and application/workflow state |
The important architectural choice is that every intake channel converges on
the same case.intake topic.
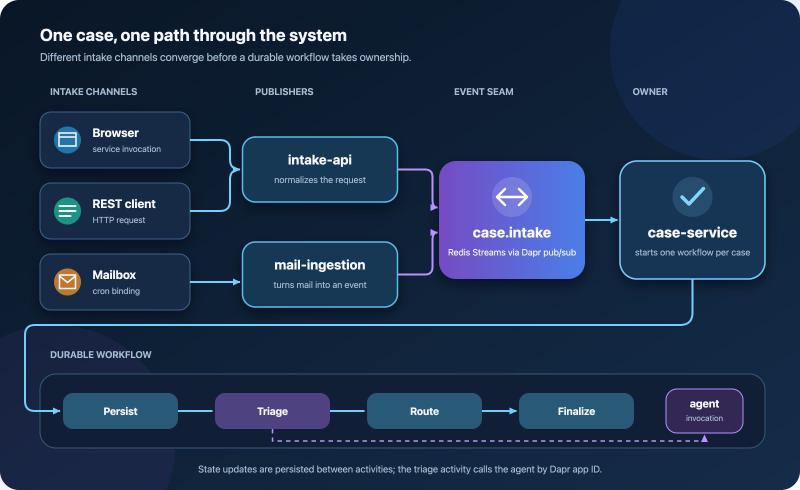
Every intake channel converges on the same event, after which one durable workflow owns the case lifecycle.
Here is how the Dapr building blocks map to the application:
| Building block | Where you see it | Backing implementation |
|---|---|---|
| Pub/Sub | Intake services to case-service | Redis Streams |
| State management | Case aggregate and a simple case index | Redis |
| Service invocation | Frontend to APIs; workflow activity to agent | Dapr sidecars |
| Input binding | Scheduled mailbox polling | Dapr cron binding |
| Secrets | Agent retrieves the OpenAI key through Dapr | Local file or Kubernetes Secret |
| Workflow | Case lifecycle and activity retries | Dapr Workflow on actors and state |
One case, from intake to completion#
By following one case from intake to completion, you can see how the individual building blocks work together instead of studying them in isolation.
Publishing one intake event#
The REST gateway accepts a case, turns it into an IntakeEvent, and publishes
it. It knows nothing about the consumer or the workflow.
# packages/api/src/ccm_api/app.py
@app.post("/cases", status_code=202)
def create_case(payload: CaseCreate) -> dict[str, str]:
    event = IntakeEvent(
        subject=payload.subject,
        body=payload.body,
        channel=payload.channel or CaseChannel.API,
        reporter=payload.reporter,
        metadata=payload.metadata,
    )
    publish(constants.TOPIC_INTAKE, event)
    return {"case_id": event.case_id, "status": "accepted"}
The shared helper contains the Dapr-specific call:
# packages/common/src/ccm_common/dapr_client.py
def publish(topic: str, data, settings=None) -> None:
    settings = settings or get_settings()
    with DaprClient() as client:
        client.publish_event(
            pubsub_name=settings.pubsub_name,
            topic_name=topic,
            data=data.model_dump_json(),
            data_content_type="application/json",
        )
The component gives casemgmt-pubsub its Redis implementation:
apiVersion: dapr.io/v1alpha1
kind: Component
metadata:
  name: casemgmt-pubsub
spec:
  type: pubsub.redis
  version: v1
  metadata:
    - name: redisHost
      value: "ccm-case-management-redis:6379"
Pub/sub is the seam that lets you add another intake channel without changing the case processor. It also introduces an obligation: delivery is at least once, so your consumers must tolerate duplicates.
Turning the event into a workflow#
case-service registers a subscription with dapr-ext-fastapi. Dapr delivers
the payload inside a CloudEvent envelope. In the handler, you only need its
data field.
# packages/case_service/src/ccm_case_service/app.py
class IntakeCloudEvent(BaseModel):
    model_config = ConfigDict(extra="ignore")
    data: IntakeEvent


@dapr_app.subscribe(
    pubsub=settings.pubsub_name,
    topic=constants.TOPIC_INTAKE,
    dead_letter_topic=constants.TOPIC_INTAKE_DEADLETTER,
)
def on_intake(event: IntakeCloudEvent) -> dict[str, str]:
    return handle_intake(event, repo, DaprWorkflowClient())
I use two deduplication checks. An existing case record is a durable inbox
marker, so a delivery after workflow completion is acknowledged without
starting again. Before that first activity persists the case, the workflow
instance ID prevents two active workflows for the same case. The handler only
acknowledges an ALREADY_EXISTS conflict; other scheduling errors propagate.
An inbound resiliency policy retries those failures five times and then moves
the message to case.intake.deadletter instead of silently losing it.
Keeping orchestration readable#
The workflow is the heart of the example. You can read it from top to bottom, while Dapr persists its progress after each activity.
# packages/case_service/src/ccm_case_service/workflow.py
_triage_retry = RetryPolicy(
    first_retry_interval=timedelta(seconds=2),
    max_number_of_attempts=4,
    backoff_coefficient=2.0,
    max_retry_interval=timedelta(seconds=30),
)


@wfr.workflow(name="case_lifecycle")
def case_lifecycle(ctx: DaprWorkflowContext, wf_input: dict):
    case_id = wf_input["case_id"]

    yield ctx.call_activity(persist_case, input=wf_input)
    triage = yield ctx.call_activity(
        triage_case,
        input=wf_input,
        retry_policy=_triage_retry,
    )
    yield ctx.call_activity(
        apply_triage,
        input={"case_id": case_id, "triage": triage},
    )
    yield ctx.call_activity(route_case, input={"case_id": case_id})
    final_status = yield ctx.call_activity(
        finalize_case,
        input={"case_id": case_id},
    )

    return {"case_id": case_id, "status": final_status}
The orchestrator must be deterministic because Dapr can replay it. Network
calls, state changes, clocks, and randomness therefore belong in activities,
not in the workflow body. In my application, triage_case invokes the agent
and the other activities update state.
With this workflow, you get three things you would otherwise have to build yourself:
- Progress survives a process restart.
- The network-bound triage activity has an explicit retry policy.
- You can see the complete lifecycle in one piece of code instead of finding it spread over several message handlers.
Dapr Workflow uses actors internally. That is why the Redis state component contains the following metadata:
- name: actorStateStore
  value: "true"
Storing the case#
The case-service owns the Case aggregate. Its repository stores each case
under case:<id> and keeps a separate JSON list of IDs because this example
does not use a store-specific query API.
# packages/common/src/ccm_common/dapr_client.py
class CaseRepository:
    def save(self, case: Case) -> None:
        with DaprClient() as client:
            client.save_state(
                store_name=self.store,
                key=constants.case_state_key(case.case_id),
                value=case.model_dump_json(),
            )
            self._add_to_index(client, case.case_id)

    def get(self, case_id: str) -> Case | None:
        with DaprClient() as client:
            item = client.get_state(
                store_name=self.store,
                key=constants.case_state_key(case_id),
            )
        return Case.model_validate_json(item.data) if item.data else None
The index is still a deliberately small demo model, but its read-modify-write
cycle now uses Dapr first-write concurrency and the ETag returned by Redis. If
another workflow changes the index first, the repository re-reads and retries
up to five times. ETag 0 gives the initial write create-if-absent semantics.
That prevents one concurrent intake from silently removing another case ID.
One small SDK surprise was that get_bulk_state(...) returns a
BulkStatesResponse. The results are in response.items; the response itself
is not the list.
Calling the agent by application ID#
The triage activity needs a synchronous response, so it uses service invocation rather than pub/sub:
# packages/common/src/ccm_common/dapr_client.py
def invoke(app_id: str, method: str, data, http_verb: str = "POST") -> bytes:
    with DaprClient() as client:
        response = client.invoke_method(
            app_id=app_id,
            method_name=method,
            data=data.model_dump_json(),
            content_type="application/json",
            http_verb=http_verb,
        )
        return response.data
The workflow calls agent by its Dapr app ID. The frontend uses the same
mechanism to call intake-api and case-service. My code does not construct
Kubernetes service DNS names. Dapr provides service discovery, tracing,
sidecar-to-sidecar encryption on Kubernetes, and built-in retries for eligible
non-streaming invocation failures. Application-level failures still need an
intentional policy; Dapr is not a reason to retry every request blindly.
Receiving a scheduled callback#
The mail service demonstrates the other traffic direction. A cron input binding calls the application every 15 seconds:
apiVersion: dapr.io/v1alpha1
kind: Component
metadata:
  name: mail-poll
spec:
  type: bindings.cron
  version: v1
  metadata:
    - name: schedule
      value: "@every 15s"
scopes:
  - mail-ingestion
The component name and route match, so Dapr invokes POST /mail-poll:
# packages/mail_ingestion/src/ccm_mail_ingestion/app.py
@app.post("/mail-poll")
def mail_poll() -> dict[str, str | int]:
    mail = _mailbox.poll()
    if mail is None:
        return {"status": "empty", "pending": _mailbox.pending()}
    case_id = _publish_mail(mail)
    return {
        "status": "ingested",
        "case_id": case_id,
        "pending": _mailbox.pending(),
    }
The scopes entry matters: only the mail-ingestion app receives this
component. I applied the same rule to pub/sub, state, and secrets, so each
sidecar only loads the components its application uses.
Being precise about the secret path#
The agent first checks OPENAI_API_KEY and only then calls the Dapr secret API:
# packages/agent/src/ccm_agent/triage.py
def _resolve_api_key(self) -> str:
    if self.settings.openai_api_key:
        return self.settings.openai_api_key
    return get_secret(
        self.settings.openai_secret_name,
        self.settings.openai_secret_key,
    )
The environment variable is an explicit override. With the documented local
and Kubernetes configurations, OPENAI_API_KEY is not set in the application
environment, so the agent retrieves it through Dapr. Locally, Dapr reads the
ignored dapr/secrets.local.json file. On Kubernetes, Dapr reads only the
selected Kubernetes Secret. The chart creates a service account per application,
grants only the agent get access to that Secret, denies the default Kubernetes
secret store, and restricts the custom store to the selected secret name. The
key is not injected into the container environment.
Running the example yourself#
You can run the commands below directly from the repository.
1. Check out and validate the code#
git clone https://github.com/jettro/dapr-tryout.git
cd dapr-tryout

uv sync
uv run ruff check .
helm lint charts/case-management
2. Run locally#
This route needs Docker, the Dapr CLI initialized for self-hosted mode, Python 3.12, uv, Redis, and an OpenAI API key.
dapr init
docker run --detach --name ccm-redis --publish 6379:6379 redis:7-alpine

cp dapr/secrets.local.json.example dapr/secrets.local.json
${EDITOR:-vi} dapr/secrets.local.json

make dev
dapr/secrets.local.json is ignored by Git. You should still check git status
before committing because a real credential should never enter repository
history.
Open the interface and the intake API documentation:
open http://localhost:8000/
open http://localhost:8001/docs
Create a case in the interface. Within a few seconds, the table should show the case moving through triage and routing. Open the case to inspect its category, priority, assigned team, suggested reply, and activity log. Also wait for the seeded mailbox cases; they prove that the cron binding reaches the same workflow.
The following screenshots come from the running application, so you know what to expect when you try it yourself. The overview combines the form for creating a case with the live case list. Status, priority, and team labels make the workflow results visible as each case progresses.
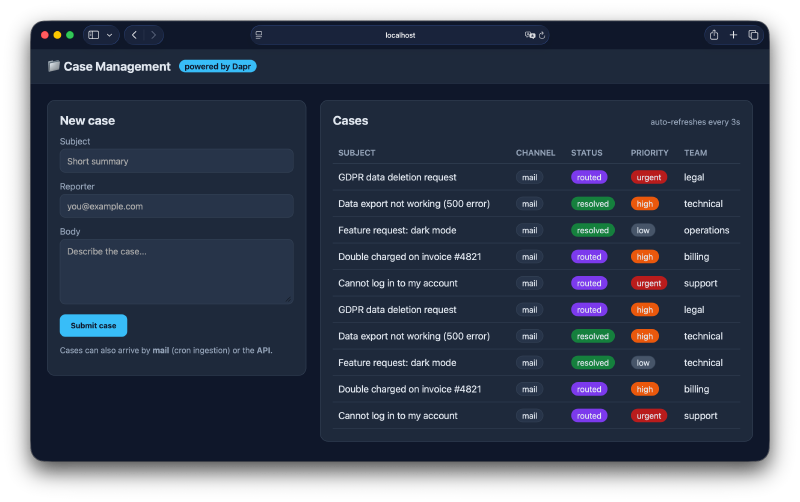
The overview screen lets you submit a case and watch cases move through triage, routing, and resolution.
Select a case to see the original request next to the agent’s triage result. The detail screen shows the selected category, priority, team, suggested reply, and the history written by the workflow activities.
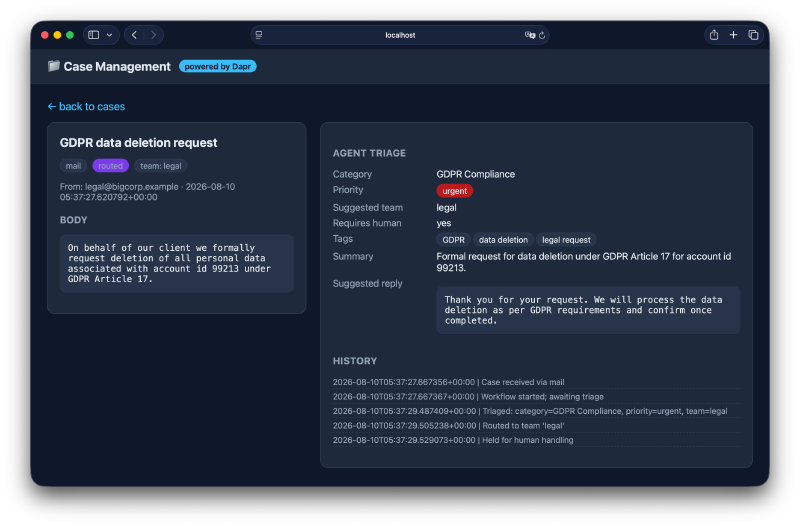
The detail screen makes both the agent’s result and the durable workflow history visible.
The equivalent API check is:
curl --fail-with-body \
  --request POST http://localhost:8001/cases \
  --header 'content-type: application/json' \
  --data '{
    "subject": "Cannot reset password",
    "body": "The reset link returns a 500",
    "reporter": "me@example.com"
  }'
When finished, stop make dev with Ctrl-C and remove the disposable Redis
container:
docker rm --force ccm-redis3. Deploy to Kubernetes#
The chart is designed for a local cluster whose container runtime can see the locally built image. I use OrbStack. Before deploying, verify your current context instead of assuming it:
kubectl config current-context
dapr init -k
make image
The deployment script creates or updates a Kubernetes Secret over stdin and makes Helm refer to it. The key does not enter command arguments or Helm release values. The script restarts the agent so a rotated key is read again:
printf 'OpenAI API key (input is hidden; paste it and press Enter): '
IFS= read -r -s OPENAI_API_KEY
printf '\n'
export OPENAI_API_KEY
make deploy
unset OPENAI_API_KEY
Now verify the deployment rather than stopping after a successful Helm command:
kubectl --namespace case-management get pods
kubectl --namespace case-management get components.dapr.io
kubectl --namespace case-management get pods \
  --output custom-columns='NAME:.metadata.name,CONTAINERS:.status.containerStatuses[*].name'

open http://localhost:30080/
open http://localhost:30081/docs
Every Python pod should contain its application container and daprd. In the
browser, create a case and watch it progress. Then open its detail page and
confirm that triage and routing results are present. Submit another case through
Swagger or curl, and confirm that it appears in the same list. Finally, check
the logs if the UI does not change:
make logsClean up the release and the separately managed secret when you are done:
make undeploy
kubectl --namespace case-management delete secret ccm-openai
What still remains before production#
This project taught me where Dapr helps, but it is intentionally a learning application. I would not present the current chart as a production template.
- I would add tracing export, dashboards, alerts, resource tuning, network policies, and a proper Redis deployment with persistence and authentication.
- The JSON case index is concurrency-safe now, but a production query model should support pagination and avoid reading every case for one list page.
- I would add a supported operational workflow for inspecting and replaying the dead-letter topic, with alerts when messages arrive there.
- I would run failure-injection and load tests against the chosen production pub/sub and state components; the included tests cover application decisions, not an actual Dapr control plane or Redis failure.
These are not reasons to avoid Dapr. They are reminders that a runtime can standardize integration mechanics without deciding reliability, security, and data ownership for me.
When I would choose Dapr again#
Dapr became useful once the example had multiple services and multiple forms of communication. I would consider it when a system needs several of its building blocks, has services in more than one language, or benefits from portable component APIs and durable orchestration.
For a monolith or one small service, the sidecars and control plane are extra moving parts. If an application depends heavily on vendor-specific features, a native SDK may be the clearer choice. And for latency-sensitive paths, I would measure the extra hop rather than call it negligible.
The main lesson for me is that Dapr moved a useful boundary. My Python services still contain the business decisions—how a case is triaged, routed, and resolved—while messaging, invocation, workflow persistence, and component connections sit behind consistent APIs. The boundary is valuable precisely because I can still see where it ends.

